
Measuring Awareness, Adoption & Trust for EVEE: JPMorgan Chase's Call-Center AI Assistant
How early discovery research on the pilot became EVEE Intelligent Q&A. What it took to scale AI maturity reliably and influence firm wide impact.
27
Agent specialties the assistant served guidance across 8500 agents and 75 million customers
32 Million
inbound calls per year supported by EVEE's guidance
After
30%
Reduction in average handle time (AHT), concentrated in the call-reason identification, clarification, and resolution phase.
EVEE Intelligent Q&A is now a publicly documented JPMorgan Chase production system (see References). This case study covers the early-stage discovery research behind it. Specifics generalized per NDA.
Overview
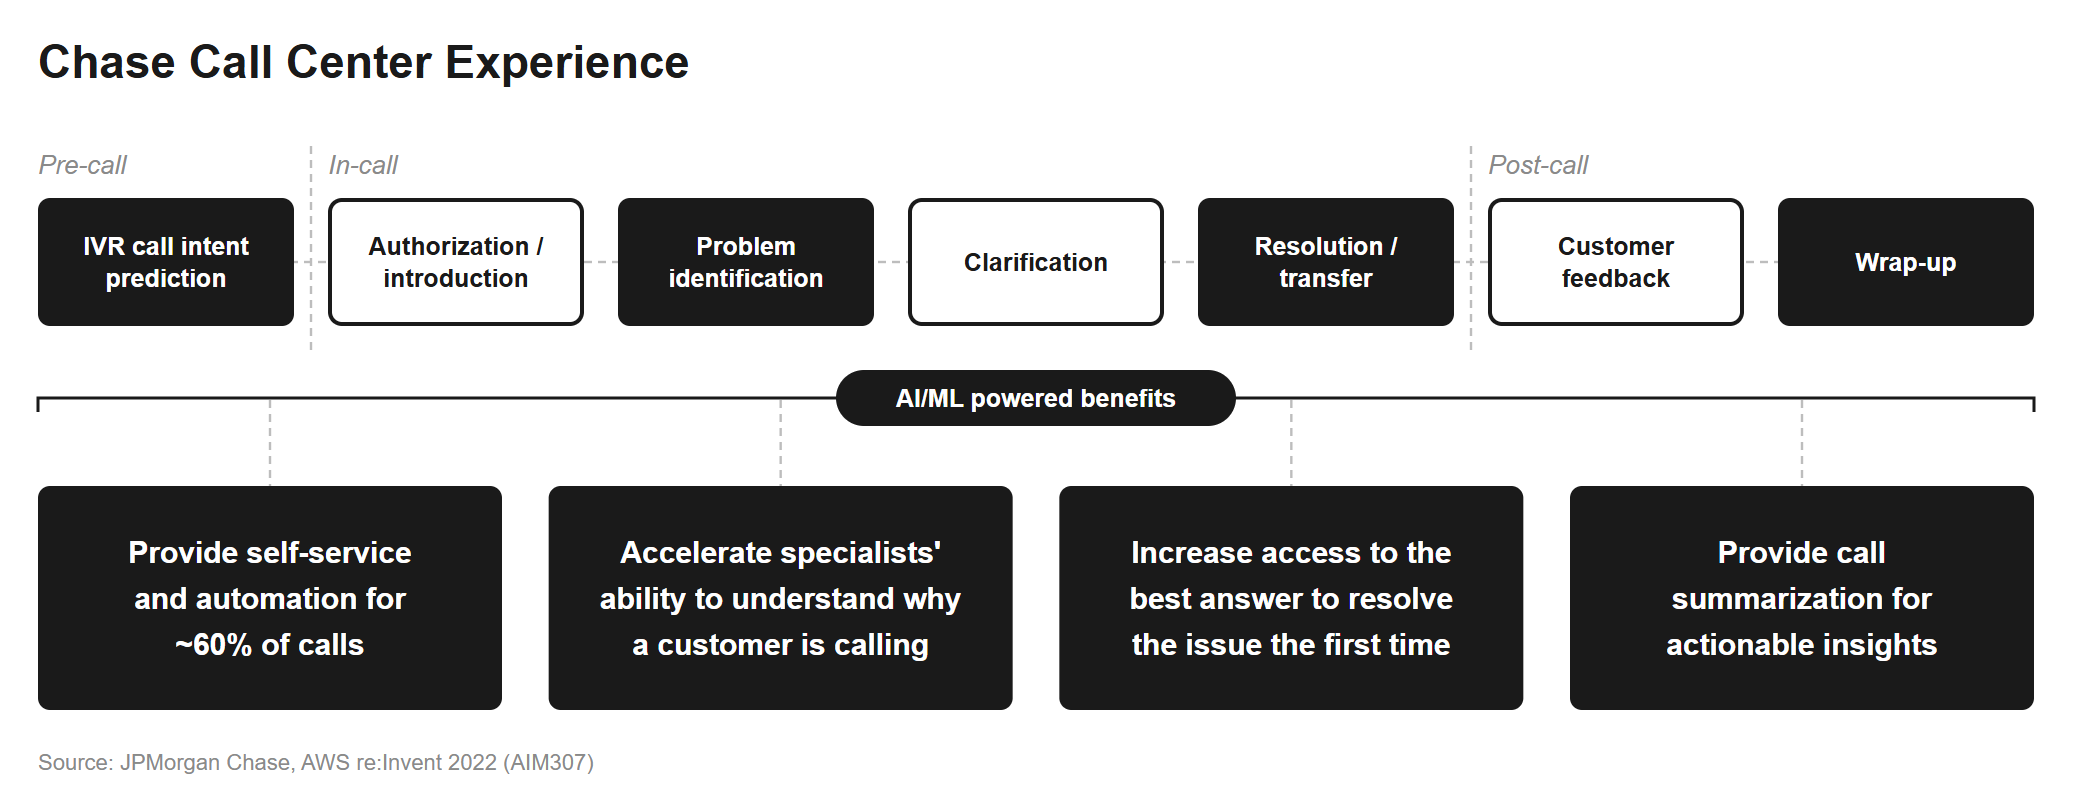
JPMorgan Chase's Digital Customer Experience (DCE) team was building a machine learning based agent assist for call specialists handling dispute, fraud, and transaction inquiries. The pilot has since scaled into EVEE Intelligent Q&A, a Gen AI in production deployed across JPMorgan Chase’s call centers. Its job was to surface and suggest the right guidance in real time within one of the most regulated and high stakes support environments in the company.
I led the research that evaluated how the assistant was actually performing inside its pilot. The research informed the organization how agents interacted with, perceive, and trusted the AI within the context they work in. These measurements later became KPIs which influenced whether the business was ready to advance the AI's capability or not. The study measured across three core pillars.
Awareness: Did specialists know the AI recommendation was there?
Adoption: Were the agents they use it during the call?
Trust: Could they trust the AI enough to rely on it?
Context
I joined JPMorgan Chase as the sole UX Research in MLIO, the product space that owned machine learning and AI for the firm. I reported up to Digital Customer Experience (DCE), the centralized organization that housed JPMorgan’s enterprise UX research. Historically research had struggled to hold in MLIO with previous researchers having high turn over and there were few established UX KPIs so it was paramount I operated collaboratively mindful of the team while building a collaborative research ecosystem that fit it’s culture and decision cycle.
We had roughly eight scrum teams under a single product owner, with an area product owners on each pillar. At the time, a 200-specialist pilot was testing an early prototype native application that delivered real-time curated guidance during live calls. The pilot's initial premise was simple: “agents now worked remotely during COVID and couldn't just lean over and ask senior staff”. Despite that premise, I had joined the business while immediately receiving reports that agent usage of the initial capability was at an all time low.
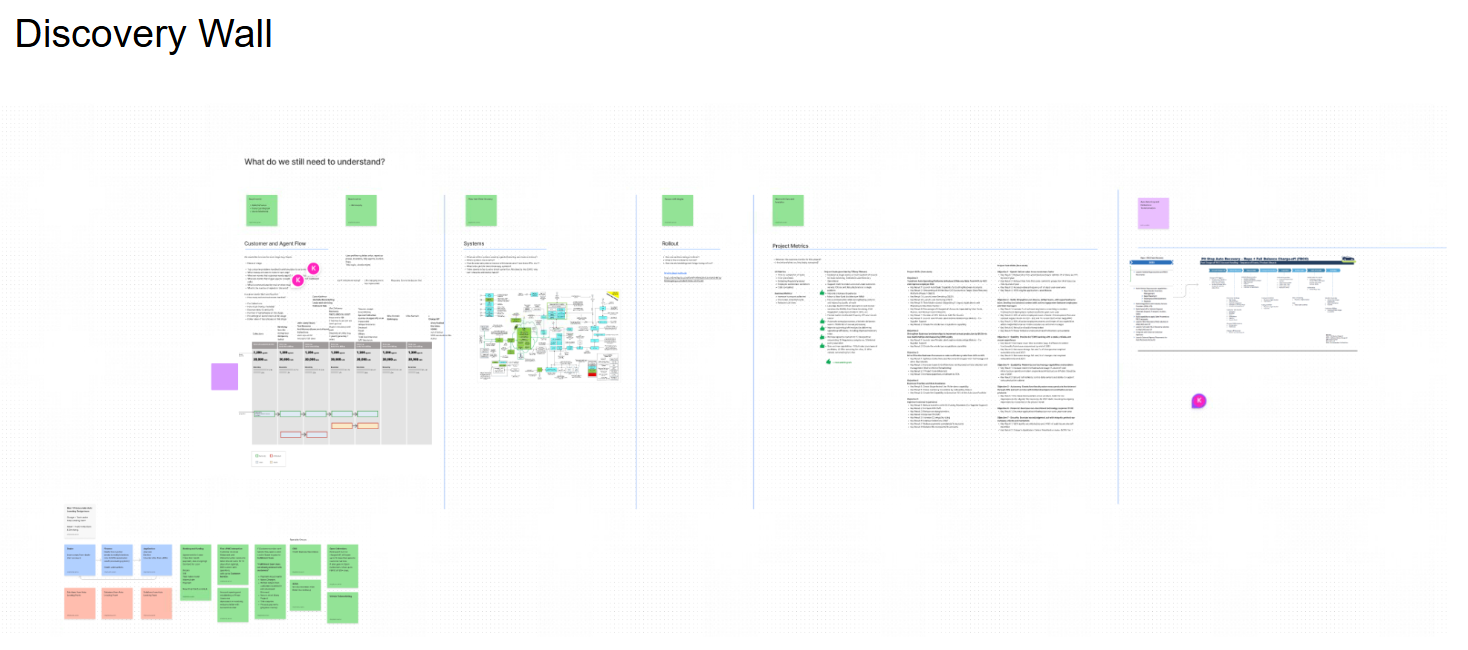
When I arrived, I compiled usage analytics of the EVEE prototype with Tableau in partnership with data science and recordings of agent screens using internal tools to lead a discovery wall and opportunity solution tree workshop collaboratively with product, data science, and design that surfaced a gap. The business knew very little about how our guidance ML/AI Models were actually performing in the field beyond that analytics models were showing low adoption and had not set a clear framework for AI progression. The output of this workshop influenced a research proposal.
Team: UX Research (me), Data Science, Product, & UX Design
My AI Strategic Maturity Framework
AI maturity is influenced by a levels-of-automation model (Parasuraman, Sheridan and Wickens, 2000) and trust calibration research (Lee and See, 2004). EVEE was climbing a capability ladder, and each rung carries a different relationship between the human and the AI:
Stage 1: Surface. The AI displays relevant information. The specialist does all the deciding.
Stage 2: Suggest. The AI actively recommends an action or answer. The specialist evaluates and chooses.
Stage 3: Assist (act with approval). The AI proposes to act and executes on the specialist's approval. The specialist supervises rather than drives.
The pilot lived in Stages 1 and 2, with a clear ambition to reach Stage 3. My thesis was that you cannot advance a stage reliably without measuring awareness, adoption, and trust at the stage you're on because each gates the next:
Awareness gates everything. If specialists don't know a capability exists in their workflow, it's invisible, and every downstream metric reads as zero. An awareness gap is routinely misdiagnosed as "the AI isn't useful."
Adoption gates trust data. You can't measure trust in something nobody uses. Awareness without adoption means the capability is seen but not integrated.
Trust gates the climb. Surfacing tolerates low trust: the human verifies everything. Suggesting needs moderate trust: the human weighs the recommendation. Acting-with-approval demands high, calibrated trust. Push to Stage 3 before trust is demonstrated and specialists either rubber-stamp blindly (a risk event waiting to happen) or reject reflexively (capability paid for and wasted).
Measuring all three at each stage is what turns "are we ready to advance?" from an executive gut call into an evidence-gated decision and gives a repeatable instrument you can re-run at every stage and every product, so AI maturity scales the same way every time instead of being relearned per team.
My Collaborative Framework
After observing the established working environment at JPMorgan, I developed a collaborative research process to align with it. Initially, that looked like the 4 step system in the image below during this study.
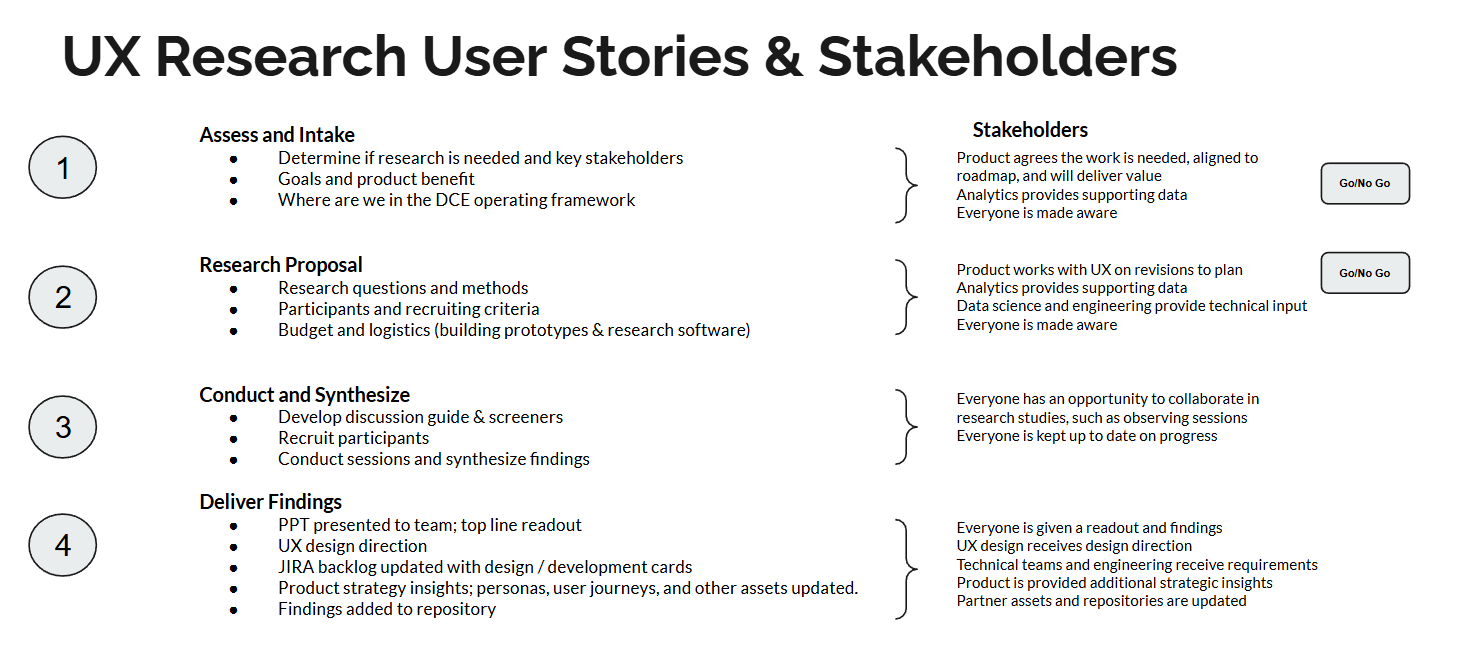
Original working artifact, JPMorgan Chase DCE, 2021.
The study
A mixed-methods field evaluation with 12 pilot participants, sampled across call-volume tiers, tenure, performance, and onshore/offshore status so findings weren't an artifact of one kind of specialist. Although 6 participants would be enough to test for themes, I intentionally chose 12 to verify if those large themes were consistent across these varied groups.
The study had five components, each pulling on a different part of the awareness / adoption / trust picture:
Initial interview and job shadow. Casual rapport-building to understand each specialist's real working conditions before observing them with an opportunity to conduct analysis on contextual observations.
Wizard-of-Oz call scenarios with discrete trials. Specialists worked real recorded calls against a Figma prototype I controlled remotely, paired deliberately to key opportunity scenario types which let me observe authentic in-call behavior without a fully built system.
Participatory design. Each specialist was invited to add one feature to their work experience which allowed us to surface needs the prototype hadn't anticipated, and deliberately not limited to the prototype itself.
A/B test with embedded discrete trials. Two prototype variants tested for preference, plus probes on what specialists thought specific features meant or did which facilitated a direct read on comprehension and trust.
Final interview. Closing reflections, and a formal channel for the team to follow up with specialists.
This was scoped intentionally as more than a prototype study with specialists empowered to raise any solution, not just prototype improvements.
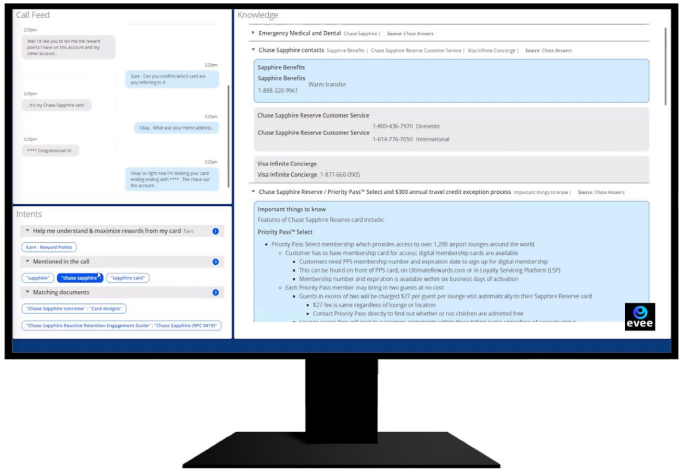
What I found
Gaps: 11 of 12 missed the guidance · 9 of 12 misread "Call Intent" Improvements Influenced: 30% lower AHT in the pilot · 12% better word error rate · 20%+ fewer "general inquiry" misclassifications
The first two findings were Stage 1 and Stage 2 failures in my AI maturity framework: the assistant wasn't visible at the moment of need, and when it was, its language wasn't trusted.
Awareness was the binding constraint.
Evidence: 11 of 12 specialists found guidance only when they went looking, and answers were often buried in the first response. The tool was hidden by users unless selected.
What changed: Recommended initial training surface to be required on the screen near-term and eventual guidance to be embedded into core workflow. Later adopted by public EVEE.
Comprehension is a trust prerequisite.
Evidence: 9 of 12 didn't understand "Call Intent," and 5 suggested "Call Reason."
What changed: We renamed it. Based on the study, the team also required EVEE on screen, where specialists previously could hide it, and lifted AHT targets from pilot specialists' performance reviews so they could use the tool without risk. With those changes in place, AHT fell 30% on calls where the model identified the call reason correctly, before the move to AWS, with the biggest gains for junior specialists. (Internal AHT-per-call tracking, pilot population.)
Too much information erodes trust.
Evidence: A/B tests on a roughly 600×600 display showed that over-surfacing hurt both usability and trust. The initial pilot population also included variable hardware and also identified users with laptops working from home without additional monitors which negatively impacted usability.
What changed: Information density was calibrated for the Suggest stage and we standardized equipment requirements including dual monitor setups for the pilot population to intentionally build for tomorrow.
Qualitative signal set the measurement agenda.
Evidence: Summarization burden and transcription errors came up repeatedly but weren't being measured.
What changed: New KPIs introduced drove investment, including the move to AWS. The program reported about a 12% improvement in word error rate and a 20%+ reduction in "general inquiry" misclassification across roughly 33 million monthly interactions (JPMorgan Chase, AWS re:Invent 2022).
Issues were fixed as they surfaced: The Design Lead and I caught and resolved a native-app wrapping problem in condensed layouts during the study itself.
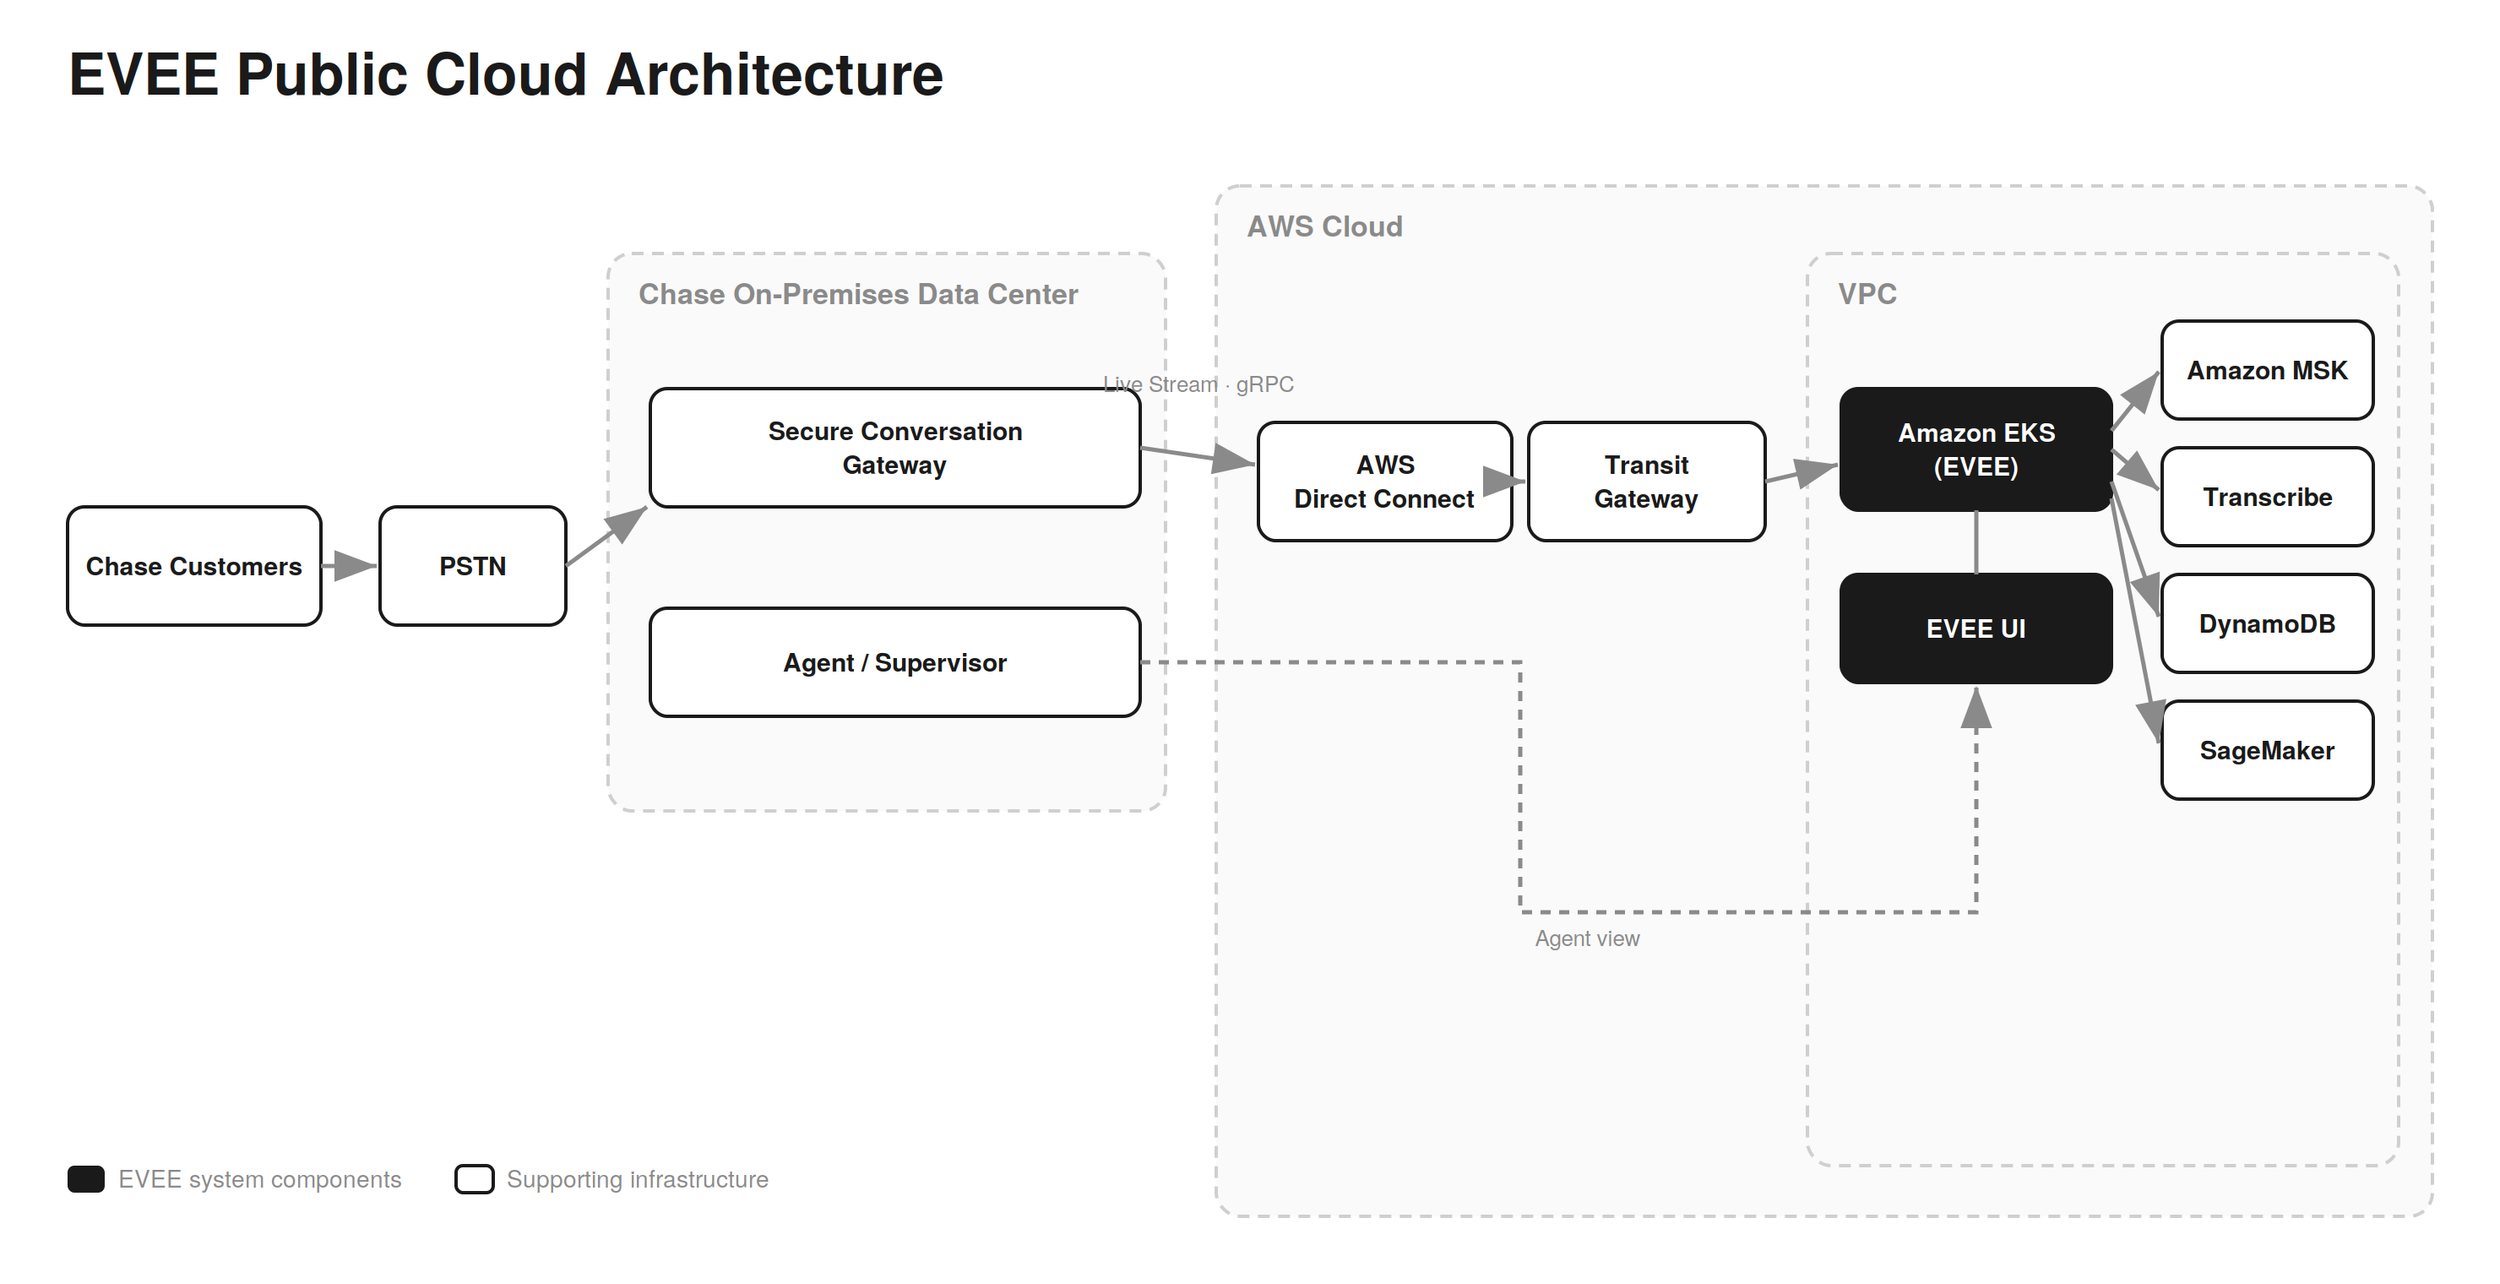
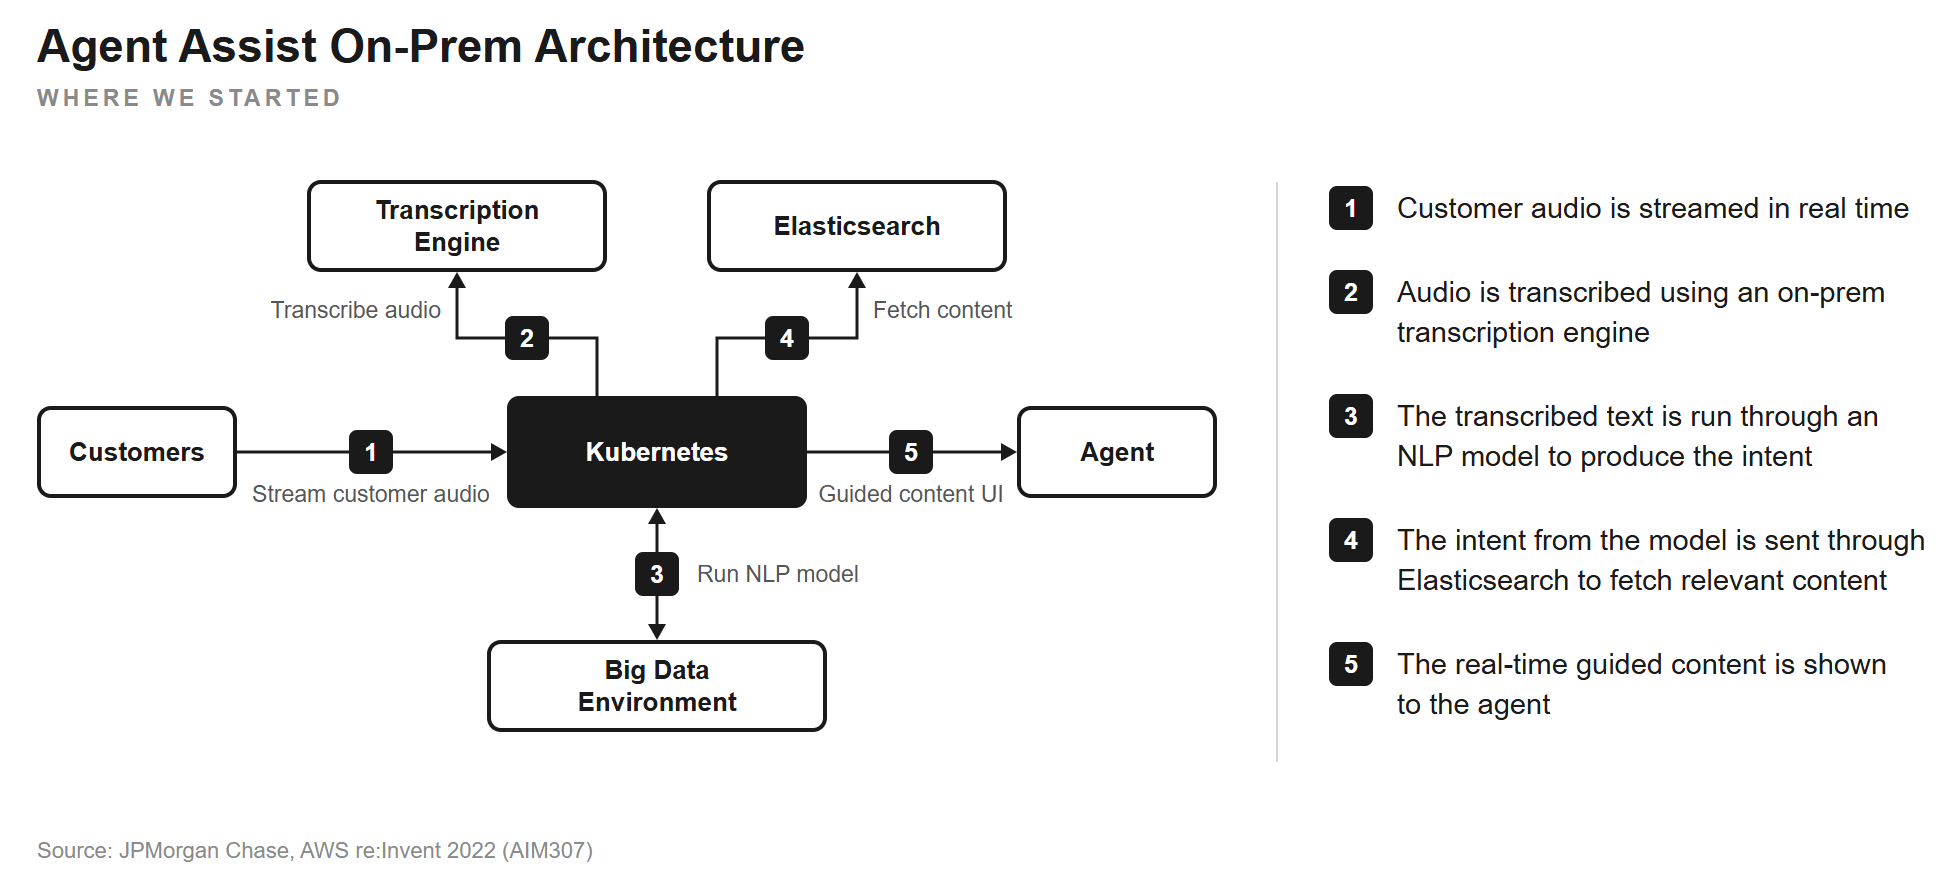
Changes to System Architecture from 2021 to 2022
Before
Reflection
What I learned. Coming into an already established AI development environment with trust issues was a firehose moment. It wasn't just about building a product. It was a gut check on how important trust and noticeability are to building solutions. If you move too fast, or your solution is ineffective, even your own employees will bury your product. These specialists were legitimately worried about their performance KPIs, including factors like average handle time, and didn't want to gamble their numbers on a tool that wasn't production ready yet. I advocated lifting traditional AHT requirements for pilot specialists until suggestions were reliably helpful, since those requirements distorted the very behavior the study needed to read. Without trust and noticeability, all your adoption and training KPIs are dust. And without the safety to train it, people won't take the risks that let it improve.
What I'd do differently. The qualitative work ultimately drove the team to stand up quantitative KPIs, but it drove them reactively, after discovery had already surfaced the gaps. Next time I'd front load that instrumentation rather than build it in response, standing up quantitative baselines on day one. Those baselines would include discovery rate, source data inspection rate, return visit rate, time to first meaningful interaction, surface to decision rate, stated confidence, and mention rate in the pilot's internal help channels. Establishing them from the start would have sharpened the study scope in advance and given a grounded baseline to measure impact against as the work moved into later stages.
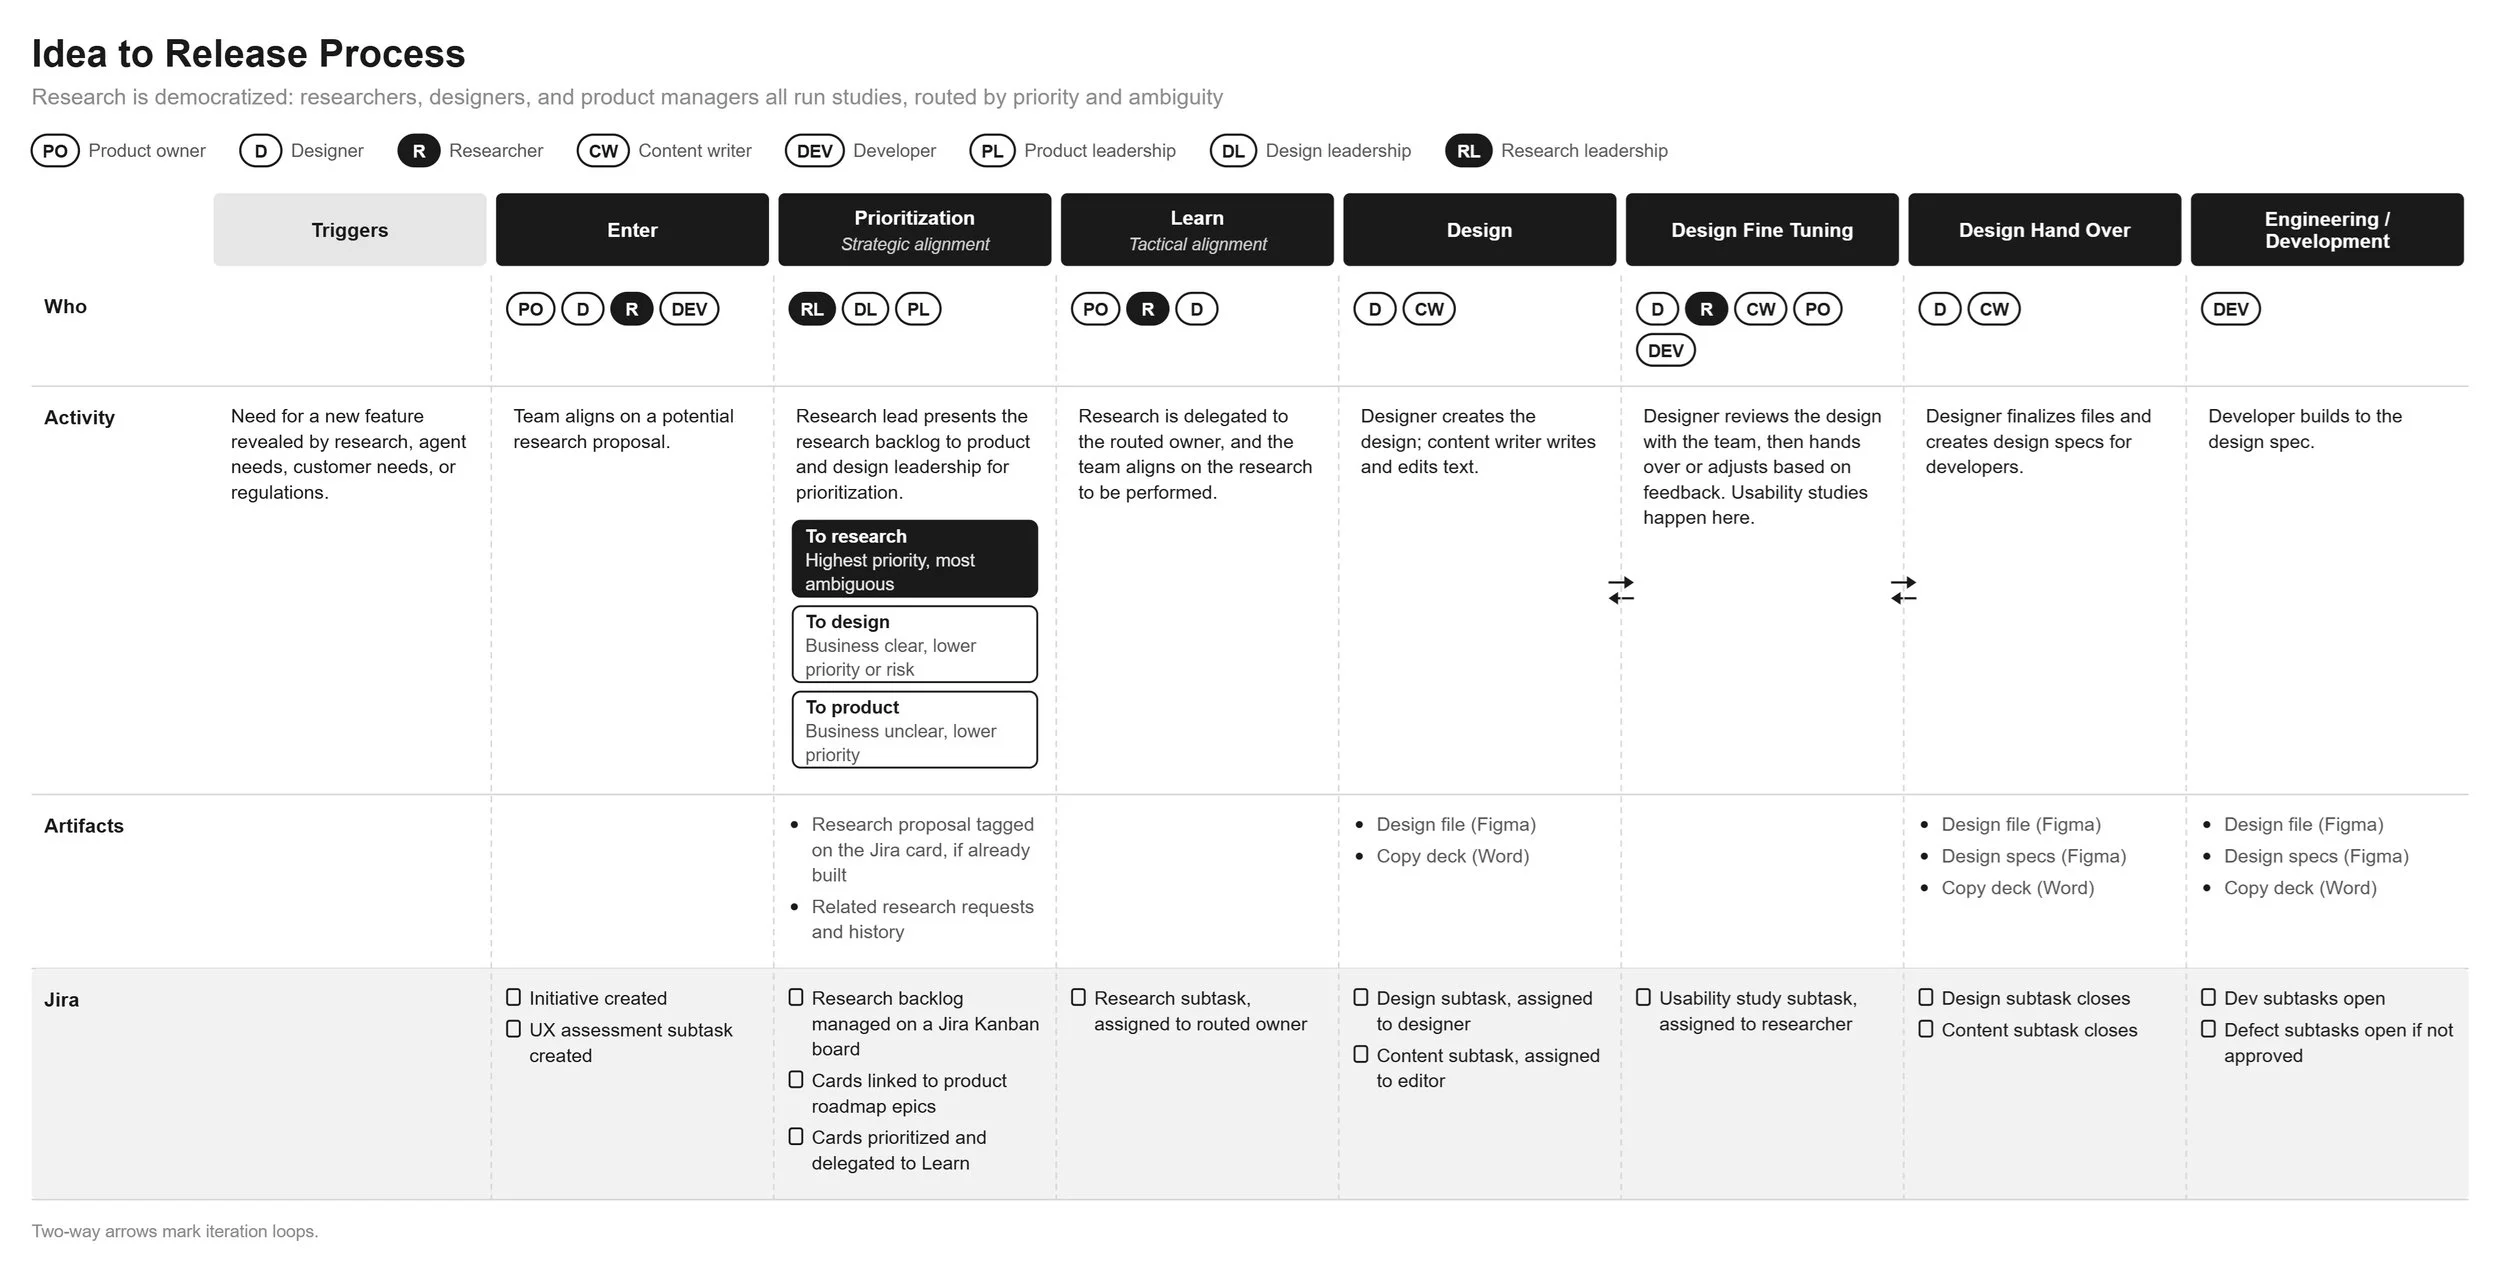
Idea to Release Process Formalization
Leveraging learnings from this and several adjacent studies, I formalized the idea to release process.
Where EVEE is today
The prototype I researched in pilot has since scaled into EVEE Intelligent Q&A, publicly reported as a production gen-AI assistant deployed across JPMorgan Chase's call centers spanning 8500 agents and 75 million customers. It’s integrated into specialists' existing tools, drawing on policy documents and transaction histories, and credited with faster resolution times and improved employee and customer satisfaction.
As the senior-most UX researcher in MLIO, I set how the team measured whether the assistant was ready to advance, and that framework shaped the pilot's roadmap. JPMorgan Chase's public AI strategy has since reportedly followed the same arc which included clear trust, adoption, and awareness KPIs as it iterates and expands on AI throughout the firm.
References
JPMorgan Chase's Real-Time Agent Assist for Contact Center Productivity, Ami Ehlenberger (MD, CTO of Machine Learning & Operations, JPMorgan Chase) & Vafa Ahmadiyeh (AWS), AWS re:Invent 2022, session AIM307 (slides)
AWS re:Invent 2022: JPMorgan Chase Real-Time Agent Assist for Contact Center Productivity (AIM307), session recording, YouTube
JPMorgan Chase's Gen AI implementation: 450 use cases and lessons learned, Tearsheet, May 2025
Case Study: How JPMorgan Chase is Revolutionizing Banking Through AI, AI Expert Network, June 2025
AI Research, JPMorgan Chase (official)
A Model for Types and Levels of Human Interaction with Automation, Parasuraman, Sheridan & Wickens, IEEE Transactions on Systems, Man, and Cybernetics, 2000
Trust in Automation: Designing for Appropriate Reliance, Lee & See, Human Factors, 2004